There are 30+ AI agent frameworks right now. You need one. Maybe two. Here’s how to pick the right one without wasting 3 months on the wrong choice.
If you’ve been anywhere near AI development in the last year, you’ve seen the explosion. LangGraph. CrewAI. AutoGen. Anthropic’s Agent SDK. OpenAI’s Agents SDK. Smolagents. Mastra. Agno. Pydantic AI. New ones every week. Each one promising to be “the framework” for building AI agents.
And you’ve probably done what most people do: read three comparison posts, got more confused, bookmarked seven GitHub repos, and built nothing.
I get it. I’ve been running a 15-agent automation system for months — a content pipeline that scans AI news, writes newsletters, generates social posts, and distributes across platforms. Every single day. I’ve used, tested, broken, and rebuilt with multiple frameworks. I know which ones deliver and which ones look impressive on a README but fall apart in production.
Today I’m going to break down the complete agent framework space. Not marketing copy — real talk about what works, what doesn’t, and which framework you should actually pick based on what you’re building.
By the end, you’ll have a clear decision framework. No more analysis paralysis.
PART 1: THE FOUNDATIONS
Section 1: What Is an AI Agent (Really)
Let me cut through the hype.
An AI agent is three things combined:
An LLM (the brain)
Tools (things it can do — search the web, run code, read files, call APIs)
A loop (it keeps going until the task is done)
That’s it. An LLM that can use tools and decide when it’s finished.
When you ask ChatGPT a question and it responds — that’s not an agent. That’s a single API call. One prompt in, one response out.
When you tell an agent “research the top 10 competitors in my market and create a spreadsheet comparing their pricing” — that’s an agent. It will: 1. Think about what it needs to do (reason) 2. Search the web for competitor info (act) 3. Look at what it found (observe) 4. Decide it needs more detail on pricing (reason again) 5. Search for specific pricing pages (act again) 6. Compile everything into a spreadsheet (final action)
This think-act-observe loop is called the ReAct pattern (Reasoning + Acting). It was introduced in a 2023 Google research paper and it’s the foundation of virtually every agent framework today.
Single Agent vs Multi-Agent
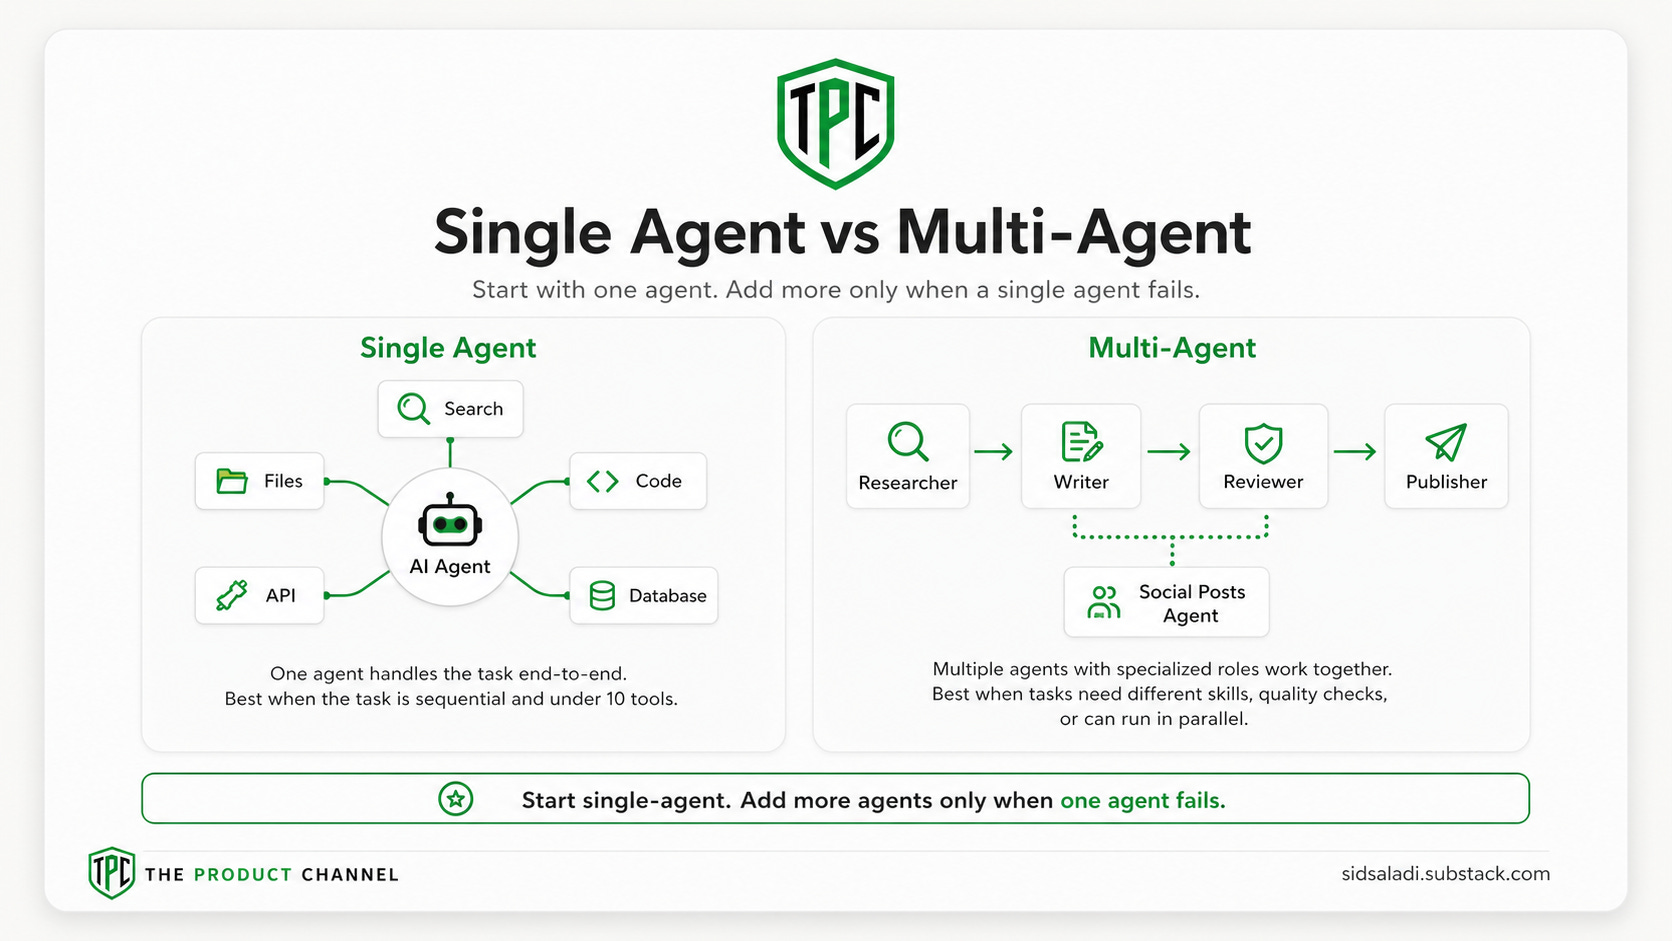
A single agent is one LLM running one loop with a set of tools. Like a solo employee handling a task end to end.
A multi-agent system is multiple LLMs, each with their own tools and instructions, coordinating on a bigger task. Like a team where the researcher hands off to the writer, who hands off to the editor.
Here’s a rule I’ve learned the hard way:
Start with a single agent. Add more agents only when a single agent fails.
Specifically — go multi-agent when: - Your single agent has 15+ tools and starts picking the wrong ones - The task requires genuinely different skills (research vs. writing vs. code review) - You want quality checks where one agent reviews another’s work - You have parallel sub-tasks that can run simultaneously
Don’t go multi-agent because it sounds cool. Multi-agent systems are harder to debug, slower to execute, and more expensive to run. A single well-designed agent beats a poorly coordinated team of agents every time.
Here’s a real number: a single customer support agent handles a ticket in 2-4 seconds. A multi-agent version of the same task takes 8-15 seconds. That’s not a benchmark from a paper — that’s production data. Multi-agent can boost performance 81% on parallel tasks, but it can also reduce performance by up to 70% on sequential tasks if you pick the wrong pattern.
The rule of thumb: if you have fewer than 10 tools, need less than 50K tokens of context, and your task is basically sequential — stick with single agent. Move to multi-agent when you’ve actually hit the walls of what a single agent can do, not when you think you might hit them someday.
When You Don’t Need an Agent at All
This is the part most framework docs skip.
You do not need an agent if: - Your task has a predictable, fixed set of steps - You don’t need the LLM to make decisions about what to do next - A simple prompt → response handles it fine - You can hard-code the workflow
A function that calls GPT to summarize text is not an agent. It’s an API call. And that’s perfectly fine. Don’t add agent complexity where a simple chain works.
The litmus test: Does the LLM need to decide which tools to use and when to stop? If yes, you need an agent. If no, you don’t.
Section 2: The 5 Capabilities That Matter
When evaluating any agent framework, these are the five dimensions that actually matter. I’ll rate each major framework against these later, but first, let’s understand what they mean.
1. Tool Use
Can your agent call external functions? Search the web? Run code? Read databases?
Tool use is the most basic capability. Every framework supports it. But the quality of tool use varies wildly: - How many built-in tools does it ship with? - Does it support MCP (Model Context Protocol) — the emerging standard for connecting agents to tools? - Can you write custom tools easily? - Does it handle authentication for external services?
MCP note: As of early 2026, MCP (Model Context Protocol) has become the de facto standard for connecting agents to tools. Anthropic launched it in November 2024, and within 18 months, OpenAI, Microsoft, Google, and Amazon all adopted it. OpenAI even deprecated their Assistants API in favor of MCP-based approaches (sunset scheduled for mid-2026). There are now 6,400+ MCP servers in the official registry.
That said, MCP isn’t without growing pains. Perplexity’s CTO publicly moved away from MCP in March 2026, citing token consumption overhead and authentication friction. The protocol’s 2026 roadmap is focused on production hardening. But the direction is clear — MCP is the USB-C of agent tools. Most modern frameworks support it natively. If a framework doesn’t support MCP yet, that’s a yellow flag.
2. Memory
Can your agent remember things across conversations? Does it know what happened last time?
Three types of memory matter:
- Short-term (working) memory: What the agent knows during a single run. Every framework has this — it’s just the context window.
- Long-term memory: Persistent storage across runs. “This customer prefers email over phone.”
- Shared memory: Multiple agents sharing information. “The researcher found these 5 articles — the writer can access them.”
Most frameworks handle short-term memory well. Long-term and shared memory separate the good frameworks from the great ones.
3. Planning
Can your agent break down complex tasks into subtasks? Can it reason about the best approach before diving in?
Good planning means: - Chain-of-thought reasoning (thinking step by step) - Task decomposition (breaking a big task into smaller ones) - Self-reflection (checking its own work and adjusting) - Backtracking (realizing it went down the wrong path and trying a different approach)
4. Multi-Agent Orchestration
Can you run multiple agents together? How?
The three main patterns:
- Sequential: Agent A finishes, passes output to Agent B, who passes to Agent C
- Parallel: Agents A, B, and C all run at the same time on different sub-tasks
- Hierarchical: A “manager” agent delegates to “worker” agents and assembles their results
Some frameworks are built from the ground up for multi-agent. Others bolted it on later (and it shows).
5. Human-in-the-Loop
Can a human intervene during an agent’s execution? Can you pause an agent, review what it’s doing, approve an action, or correct a mistake before it continues?
This matters more than most people think. In production, you rarely want agents running completely unsupervised. The ability to pause, inspect state, approve high-risk actions, and resume is what separates toy demos from real systems.
Section 3: The Framework Map
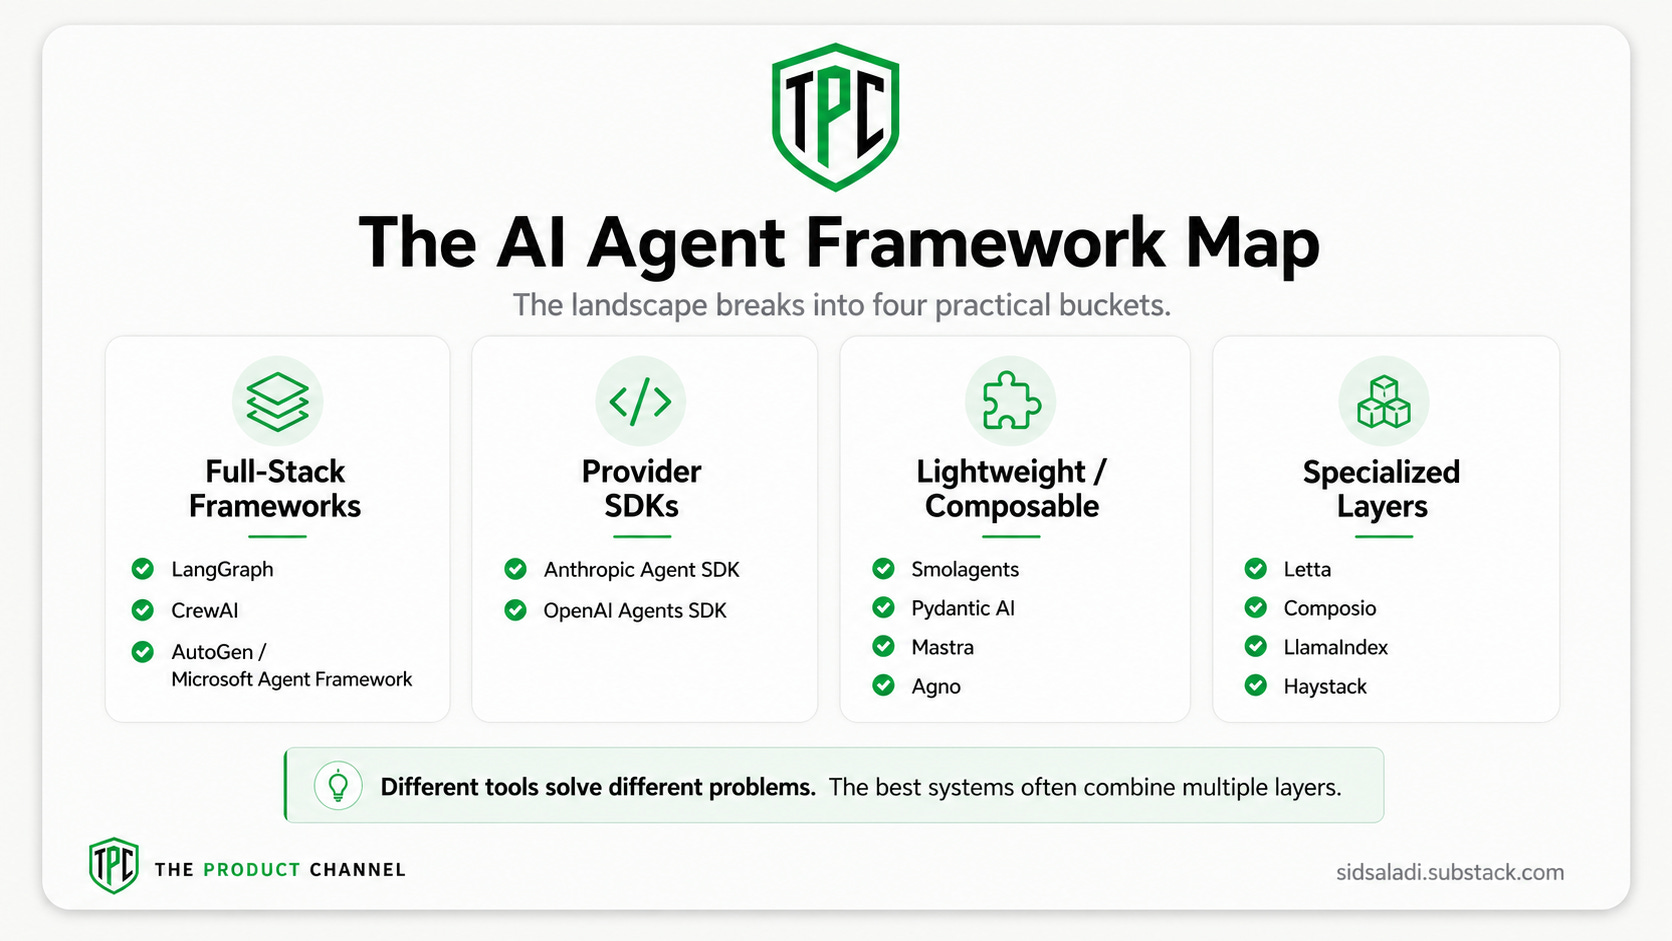
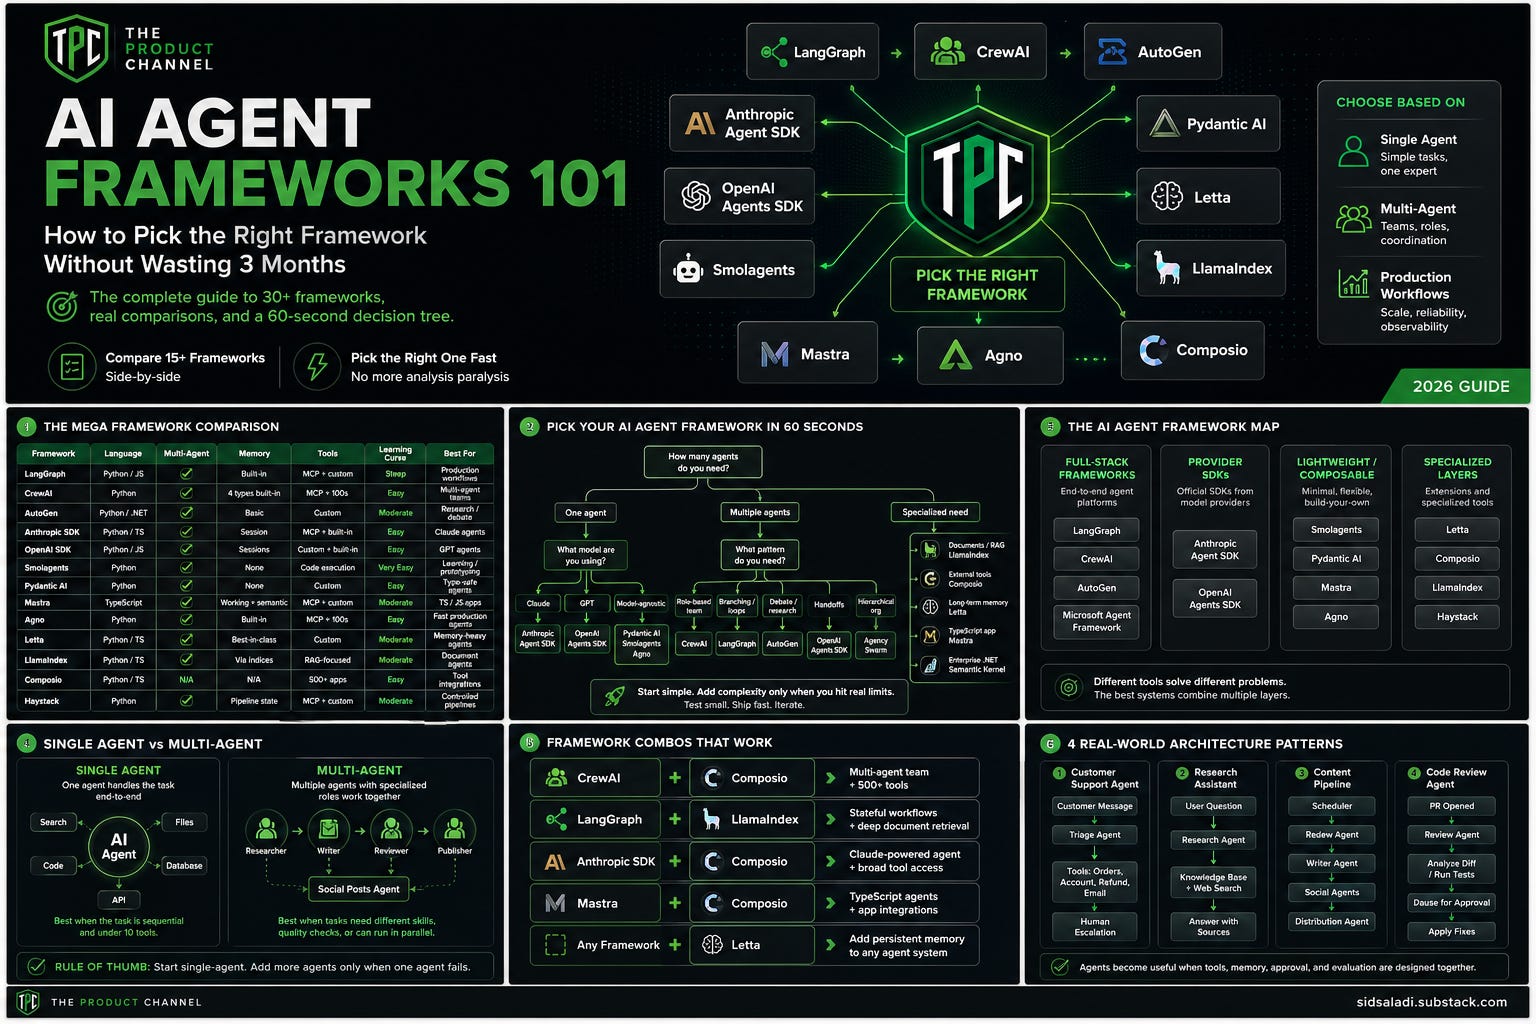
Before diving into each framework, here’s how the space breaks down:
Category 1: Full-Stack Frameworks These are the big, feature-rich platforms. They handle everything — agents, tools, memory, orchestration, deployment. → LangGraph, CrewAI, AutoGen/Microsoft Agent Framework
Category 2: Provider SDKs Built by the model providers themselves. Deeply integrated with their specific models, but often locked to that provider. → Anthropic Agent SDK, OpenAI Agents SDK
Category 3: Lightweight / Composable Minimal frameworks that give you building blocks without the overhead. Less magic, more control. → Smolagents, Pydantic AI, Mastra, Agno (formerly Phidata)
Category 4: Specialized Frameworks that do one thing exceptionally well. → Letta (memory), Composio (tool integrations), LlamaIndex Agents (RAG), Haystack (pipelines)
Let’s go through each one.